This document provides introductory material to indexing concepts for disk based access.
GOAL
Find a piece of data fast, even though the data is on disk
The fact that data is disk has serious implications for performance. why?
Concept
Physical Data Management in Databases:
Databases store records. Each record is a fixed length item that contains multiple data primitives. The structure of a record is usually specified by a schema.
Databases love fixed length records. Again, this has implications because of disk storage. Why are fixed length records preferable?
Example
Relation ski( brand str(10), name str(10), lenght int, rocker bool )
Assume chars take a byte, int takes 4 bytes, bool takes a byte (why not a bit?). Each record requires 25 bytes. 3 skis take 75 bytes.
The database creates a file for the data in each relation. Here is how the file might look for 3 skis:
k2________Apache____00B20Dynastar__Cham______00B71Atomic____Arc_______00CB0
The integers are 178, 183, and 203 in hex.
The data file is essentially an array of records such that the structure of each record is known. The easiest way to find something in an array is to search it! A good way to search an array is to sort it, then use a binary search. There is only 1 problem:
We cannot use a traditional sorting technique. Why?
The solution is to use an external memory sort. We will use an external merge sort. The basic question is “How can we sort :math”X bytes of data in  bytes of memory”?
To do this, we want to maximize disk performance by playing to its strengths, and maximize memory performance by playing to its strengths.
Disk strengths are
Memory strengths (that we want to take advantage of):
Here is the basic algorithm:
External Merge Sort Algorithm. Sort  bytes of data in bytes of memory.
 files (be careful about the remainder)
For each file
 , read bytes of data into memory, sort it, and write to

That is the sort step, it creates a bunch of sorted files.
 input buffers, and one output file named
 Each buffer will hold data from 1 file in F.
Fill each buffer with data from its corresponding file
Until all files are empty, find the smallest value at the front of an input buffer, remove it, put it in the output buffer.
That is the merge step
Exercise
What is the time complexity and space complexity of merge sort?
So, the approach to indexing a file using a sorted file is to sort, then simply do a binary search
Example
The original data file above is sorted on ski length. How do I find the record containing the 178cm ski?
Problems:
One of the major problems with sort indexing is that the file itself is the index. The file and index are integrated! This has a lot of not-so-nice implications and restrictions.
Lets remove the index from the actual data. lets have 1 data file, and 1 index file. We need a way to associate an record with something in the index file (we don’t want to duplicate a potentially huge relation)
Concept
Key. A key is a unique identifier for a record in a relation. Usually, it isi desirable for the key to be much smaller than the record in terms of data size. The key and record form a key/value pair.
Relations come with a built in concept of a key, a primary key for the relation. So, we simply need a hash table that takes a key, and returns what? (not a record)
For our previous example, assume ski names are unique. We want to search based on ski names. Instead of sorting the whole file, just create a hash table H. Remember, a new tuple starts at multiples of 25:
H['Cham']   -> 25
H['Apache'] -> 0
H['Arc']    -> 50
Exercise
One common criticism of hash tables is that they wast some space because you always need a little extra room in a hash table to control the number of collisions. It turns out that the wasted space is actually pretty small. In your language of choice, write a simple hash table that hashes integers to locations in an array. The simple recipe for a good hash function is here : http://www.cs.siue.edu/~marmcke/docs/cs340/hashing.html#good-hash-functions.
Once you have the hash table, try inserting objects into a hash table of length 4 until you get a collision. How many insertions did you get before a collision occurred? repeat 10 times.
Increase the size of the hash table to 100, and repeat the above experiment. You should find that you generally get a pretty full table before things start colliding.
You should find that in practice, with a properly designed hash function, the criticism is unfounded since the extra space required is actually quite small. In fact, hash tables are one of the most useful data structures out there, and have made possible much of the big data movement (as we will see).
Issues:
Hash table indexes are nice, but we want something a little more predictable.
For a quick review of basic disk concepts, and more information on B+ trees, see the following: http://www.cs.siue.edu/~marmcke/docs/cs340/trees.html#b-trees
B trees and (more commonly used) B+ trees are the answer to the problems with hashing. They provide:
B trees and their variants are used in virtually every DBMS out there.
Again, we need a concept of a key that uniquely defines a record. We will store complete records in one file (the relation). We will create a new file to hold the index. The index will contain keys that identify records, and the disk address of that record in the relation’s file. This means we don’t need to re-order the relation’s data file ever, we can simply append to it. Also, we can create as many index files as we want for whatever we want to search on.
We will talk about B+ trees, they are easier to use and manage, and work more naturally.
B+Tree
A B+tree contains 2 types of nodes: internal nodes and leaf nodes.
A node is fixed size. Usually, a node is the size of a disk page. Sometimes it will be a multiple of the size of a disk page. This means the number of items stored in a node is dependent on the size of the item, and the size of the disk page (usually 4k).
let  be the branching factor of nodes in a B+tree. indicates the number of child nodes for a node in the tree. Let
 be the actual number of keys in a node. For internal nodes
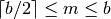 . For leaf nodes:
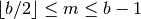 . Exceptions are made for the root node if there are simply aren’t enough items in the tree to reach the minimum threshhold.
Node Structure: Each node contains the following structure: [pointer, key, pointer, key, pointer, ..., key]. Pointers in internal nodes point to other nodes. Pointers in leaf nodes contain disk addresses, expect for the last pointer which points to the next successive node to the “right” in the tree
Note in B+ trees, keys are repeated in internal nodes and in leaves. This means every key will show up in a leaf. Some keys will show up in internal nodes. This is a major difference with standard B Trees
Searching the tree. Search the tree like a binary search tree
Insertion Into the Tree
 .
 in the left node, and all keys
 in the right node. up to the parent node of the split node, and connect the tree. If there is no room for the median value in the parent node, repeat steps 4-5 on that node
B and B+trees are complete trees. They do not grow at the leaves, instead, they grow from the root!
Example
Put the following keys into a B Tree and a B+Tree. Let the branching factor  :
20 5 8 40 23 31 1 10 33 41 22 7 16 44 27 35 11 9 2 17
How many nodes are visited to find the value 20? 33? 44?
How many nodes are visted to traverse the tree starting with value 31?
what is the time complexity of search and insert?
The algorithm for searching and inserting into a B+tree is straightforward, but the implementation of insertion can be tricky. In the worst case, a split can propogate up the entire tree to the root. It is useful to keep track of a stack of node pointers that lead back from the node of insertion ot the root.
As with most trees, the time complexities of the tree are dependent upon th tree height, for B+trees, the tree is always balanced, but trees with more full nodes might be shorter than trees holding the same amount of data with less full nodes.
For example, a B+tree with branching factor and height  can have :
 pointers to data records. why?
 pointers to data records. why?
 elements of
 , meaning logarithmic search, insert and delete!
Example
Assume a 4096 (4Kb) disk page and records with integer keys (4 bytes). Assume a 64 bit system (8 byte memory pointers). If B+tree blocks contain no header information, the we have 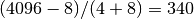 keys per block (1 pointer and 1 key takes 12 bytes. the -8 is for the last pointer).
Lets assume a typical block will have 255 keys (somewhere between 340 and 340/2=170).
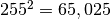 records
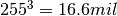 records
So, such a B+tree with height 3 requires 3 disk accesses to search 16.6 mil records! Furthermore, the top few levels of a B+tre are typically buffered in memory, eliminating the need to disk access in may cases.
The whole point of indexing is to speed up queries (since disk is slow). In an RDBMS, queries are usually SELECT FROM WHERE queries. Here are some common query types: